Comparison

Alloy vs Nominal

Nominal is built for the test you run a thousand times. Alloy is built for the question nobody planned to ask.

Nominal keeps one record of every test and lets engineers review it. Alloy's agent investigates the run that broke the pattern, explains why with the evidence, and remembers the answer for the next person who asks.

Last updated

Advanced NavigationTen tests a week instead of two

Alloy

Alloy is the AI Robotics Engineer. Its agent investigates robot and hardware data alongside your tickets, code and documents, returns a likely cause with the evidence behind it, and builds a knowledge base your whole team reuses.

Best for

Choose Alloy when your tests, robots or missions keep changing, and the work is finding out what went wrong and why.

Nominal

Nominal is a software suite to test and operate hardware. Nominal Core brings test data management, analysis, live monitoring and reporting into one workspace. Nominal Connect runs Python test apps at the edge, from lab benches to air-gapped test ranges.

Best for

Choose Nominal when your priority is one record and live view of repeatable test campaigns, with test stands and government or on-prem deployment.

Alloy and Nominal at a glance

Both products help engineers understand hardware data. Compare what each one assumes about your tests, and what your team has when the work is done.

Your team’s jobAlloyNominal
Product philosophyAgent-first from day one. The agent does the investigation end to end, in production today.A test data platform, with SQL, APIs and an MCP server for your own agents. An AI Analyst was announced in April 2026.
Data it starts fromRobot and hardware test data, including MCAP, ROS bags, flight logs and telemetry, read alongside tickets, code and docs. We build the converter for your custom log formats.Test rig data, with connectors for LabVIEW, TestStand, VeriStand, MATLAB and Python.
What a session leaves behindA likely cause with evidence linked to the moment in the recording, a next step, and a Jira ticket if you want one.Test data, plots and reports in one workspace, ready for an engineer to review.
Shared knowledge baseNotes, saved scripts, runbooks, and every past case with its outcome, reused on the next case.One record of test data across the program.
Check every new runScenarios and recurring reviews check each new run against your team's own checks, and write up what stood out.Live monitoring of tests as they run.
Capture at the edgeAlloy Edge captures or collects recordings on the robot, automates uploads, and syncs them to Alloy for investigation.Nominal Connect runs Python test apps at the edge and syncs the data to Nominal.
Use the data elsewhereMesh Storage with Parquet and Iceberg access, a Python SDK for training and internal tools, and MCP for Claude, Codex and Cursor.A SQL endpoint, REST, Python and TypeScript SDKs, and an MCP server.
Scale across the teamSupport, validation and engineering work from the same investigation and the same knowledge.A shared workspace for test, operations and manufacturing engineers.
Keep it workingAlloy maintains the models, routing, provider failover and the agent's tools.Nominal runs the platform. Your engineers write the Python test apps and set up the analysis.
Roll it outForward-deployed engineers set up the first investigations and stay until the whole team uses it.Enterprise contracts through Nominal's sales team.
Time to a first answerA first investigation on your own data in week one, often on day one.Time to a first analysis is not published.
Built for the test you repeat, or the question you didn't plan

A test data platform assumes the test is the stable thing. You define the channels, the limits and the views once, then run the campaign again and again. Every new run fits the shape you built, and the shape pays for itself across thousands of runs. That is where Nominal is strong.

Robotics and frontier hardware teams rarely get to work like that. The robot changes every week. The second flight looks nothing like the first. A field failure arrives as a customer complaint, not a test ID. When the test moves, the view built for last week's test doesn't answer this week's question, and an engineer still has to work out what changed.

Alloy starts from the question, not the test definition. Ask why a unit failed on its third run, and the agent works out which runs, signals and documents matter, compares them against runs that passed, and shows its work.

And when the test is stable, Alloy works there too. Scenarios check every run of the campaign against your team's own checks, and flag the one that broke the pattern before anyone opens a plot.

Ask Alloy
Unit 7 passed the same bench test 40 times, then failed on run 41 after the firmware update. Find what changed and show me the evidence.

Agent-first from the ground up, not an analyst added to a data platform

Alloy was built for an AI agent to do the investigation. The data layer, the robotics tools, the knowledge base and the integrations all exist so the agent can find the runs, read the evidence and finish the job.

Nominal built a strong data platform and is now adding AI to it. Its developer platform gives your own agents access through SQL, APIs and an MCP server, and it announced an AI Analyst inside Nominal Core in April 2026. That gives your agents good access to the data. Someone still has to build, test and maintain the agent that uses it.

That agent is where the results come from. The same frontier model does better or worse depending on the system around it: the data it can reach, the tools it can use, the context it receives, and how it checks its work. Alloy's harness gives the agent robotics tools, context from your past investigations, and proven checks it can reuse. We test every change on real robot investigations before it ships, and we maintain it as better models arrive.

We publish how frontier models perform on real robot investigations inside the Alloy agent: the Robotics Engineering Benchmark, with score, cost and speed for every setting.

Ask Alloy
Check every new run from this week's test campaign for the overcurrent pattern we saw last month, and tell me which units need a person.

Judge it by what you have when the work is done

A test record tells you what happened. The engineer who opens it still has to decide what it means, write it up, and hand it to the team that owns the fix.

Alloy's agent does that part. It returns a likely cause with each finding linked to its evidence, down to the moment in the recording, and says what it could not confirm. It can create a Jira ticket with the findings, follow your runbooks in Confluence, and turn the investigation into a report that a teammate can inspect and question.

Ask Alloy
Compare the failed validation runs with the ones that passed. Create a report with the likely cause and the evidence, and draft a Jira ticket for the firmware team.

Solve it once. Your team's knowledge base, written by every investigation.

As a program grows, more people ask the same questions about more units and more configurations. A record of every test keeps the data. It doesn't keep what the team worked out from it. That still lives in a few senior engineers' heads, and every repeat question goes back to them.

Alloy builds a shared knowledge base for your team: what each test is for, what normal looks like, which deviations are deliberate, your scripts and runbooks, and every past case with its outcome. Correct the agent once and ask it to remember. The next answer uses the correction, for everyone.

The tenth investigation is better than the first, because your team's knowledge is in the system, not waiting on the person who has it.

Scale with the program, not with engineer hours

When the work is reviewing plots, more units and more tests mean more engineer hours. That is the point where many teams find their tooling stops keeping up.

Alloy takes the first pass. Scenarios check past runs and new uploads for patterns your team cares about, and recurring reviews flag the run that needs a person before anyone reports it. Support and validation can investigate from Slack, so engineering gets an investigation already under way, not a question.

Buy the outcome, with people accountable for it

A platform gives your team the tools. Getting value from them is still your team's project: building the views, writing the checks, and showing everyone how to use them.

With Alloy, our forward-deployed engineers do that work with you. They connect your data, set up the first investigations against real failures, and stay until the whole team uses it, not just one champion. We also maintain the agent: new models are tested on robotics tasks before they ship, and provider failover keeps investigations running. Your engineers work on the hardware. We keep the agent working.

Test it on the run that broke the pattern

You can find out in a week whether Alloy fits your team. Use a real failure, not a demo dataset.

  1. Pick a recent failure

    Choose one issue that took your team days to explain, ideally one where the test or configuration had changed.

  2. Bring the data and the context

    Share the recordings and whatever context exists, such as test notes, firmware version and the ticket. Our engineers help you connect it.

  3. Check it, correct it, run the next one

    Check each finding against the evidence it links to. Tell the agent where it was wrong and ask it to remember, then give it the next failure.

If the agent can't give you a pointed answer by the end of the week, you have lost a week, not a contract.

When to choose Alloy or Nominal

Choose Alloy when

  • Your tests, robots or missions change faster than anyone can rebuild the analysis.
  • The question starts in the field or at the bench, and someone needs the cause, the evidence and the next step.
  • You want new runs checked automatically, and a knowledge base that keeps what your team learns.
  • You want a vendor accountable for the outcome, not another platform for your team to staff.

Choose Nominal when

  • You run large, repeatable test campaigns, and the main need is one record and a live view of every run.
  • You need test stands at the edge, including air-gapped ranges, with Python test apps operators can run.
  • You need government cloud or on-prem deployment, and your instruments already use LabVIEW, TestStand or VeriStand.

Use both when

Keep Nominal as the record for your stable test campaigns, and use Alloy for the investigations around them: field failures, changing prototypes, and the questions a test record can't answer. Alloy finds the run that broke the pattern; Nominal keeps the record of every test.

What teams have achieved with Alloy

Published results from teams running Alloy in production.

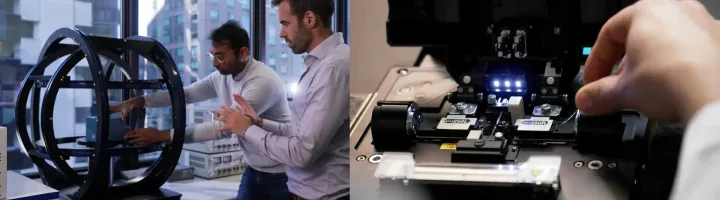
Advanced Navigation using Alloy across validation missions
Validation

1 day→10 min

Field-test analysis and reporting

Ten tests a week instead of two

Data-supported customer answers moved from one or two days to the same day.

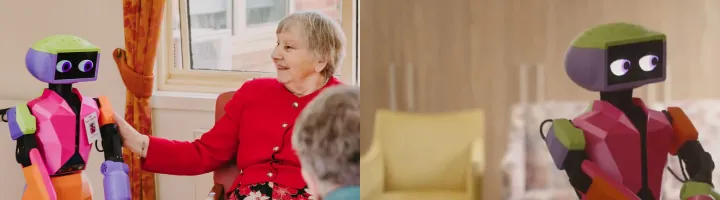
Andromeda's team and their Abi companion robot
Help desk

2 days→10 min

Investigating one fleet-wide audio bug

Alloy answers the help desk first

Alloy runs the first investigation on around 200 help desk conversations a week, so L1 and L2 support no longer waits on an engineer.

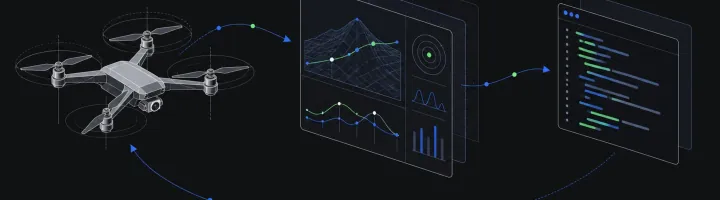
Flight data from DroneForge's drones flowing into analysis and code
DroneForgeFlight review

3x faster

Development loop: flight, investigation, code change, check

From a customer flight to a verified fix

Across 300+ deployed drones, DroneForge moves from a customer flight to an investigation, a code change and a check against future flights, with Alloy and a coding agent working together.

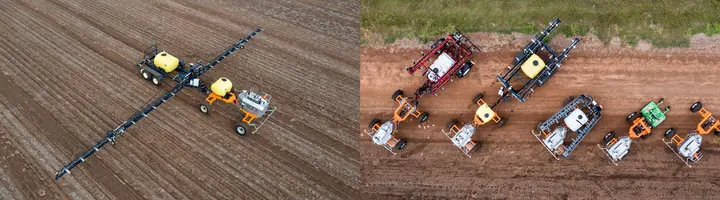
SwarmFarm's autonomy team and one of their farm robots
SwarmFarmField support

1 day→< 1 hour

Support investigation

Support grows with a fleet of close to 300 robots

A senior autonomy engineer's own estimate, a year apart. Support capacity now grows with the fleet, not the engineering team.

Questions teams ask before choosing Alloy

Does Nominal already have AI?

Nominal acquired Fid Labs in April 2026 to build an AI Analyst inside Nominal Core, and its developer platform offers an MCP server, SQL and APIs so your own agents can reach the data. Alloy's agent is in production today: at Andromeda it runs the first investigation on around 200 help desk conversations a week. The difference is what the run leaves behind: data your engineers review in Nominal, a supported answer your team keeps in Alloy.

We already use Nominal. Where do we start?

Start where your engineers' time goes: the investigations. Bring the recordings for one recurring failure, and Alloy connects to the storage you already have or provides Mesh Storage. You can keep your test record where it is while you decide from the result.

Does Alloy work for hardware test teams, not just robots?

Yes. The agent reads MCAP, ROS bags, flight logs and telemetry, and our engineers convert custom log formats on the way in. Teams building navigation systems, drones and other frontier hardware use it for validation and field investigations. Advanced Navigation runs its field-test analysis in Alloy.

Who keeps Alloy's AI up to date?

We do, not your best engineer. Alloy tests each new model on robotics tasks with known answers, moves each job to the model that tests best, runs failover across providers, and maintains the tools and integrations around them. When something breaks or a model changes, fixing it is our job.

How does Alloy keep our engineering knowledge?

Alloy's shared knowledge base keeps what your team learns: known issues and fixes, notes you ask it to remember, scripts, runbooks, and every past case with its outcome. Saved reports keep the evidence, and recurring checks keep the queries and thresholds behind them. Your team can read and correct what it keeps, and Alloy says when it uses something, so a known issue gets a known answer.

How long until we see value?

Days, not months. Teams get value in their first week, often on day one. Connect the data you already record, bring a recent failure, and watch the agent investigate it. Our forward-deployed engineers set up the first investigations with you, so there is no long implementation project before the first answer.

Who helps us roll it out?

We do. Our forward-deployed engineers work with your team to identify an initial workflow, connect the relevant data and systems, and refine the investigation against real examples. We agree on which investigations to support first and how to judge whether they are working, and we help the wider team adopt it, not just one champion. You are buying the outcome, with people accountable for it, not just software.

How should we evaluate Alloy alongside Nominal?

Bring a failure from a test or mission that had changed, and the report your team needed. Compare time to a supported answer, whether another teammate can continue the work, and how much setup each tool needed first. If you keep both, include data access and total operating cost.

Bring the failure your engineers keep getting asked about

Choose a recent failure from a test that had changed. See Alloy investigate it, check every finding against its evidence, and set up the check that catches it next time. Our forward-deployed engineers set it up with you, and teams get value in week one, often on day one.